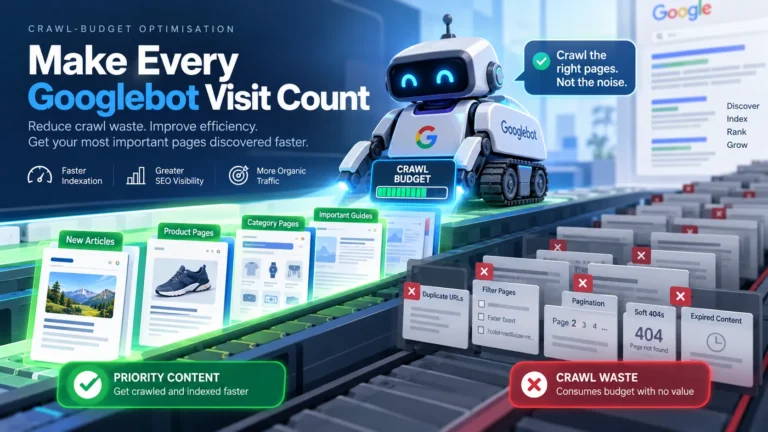
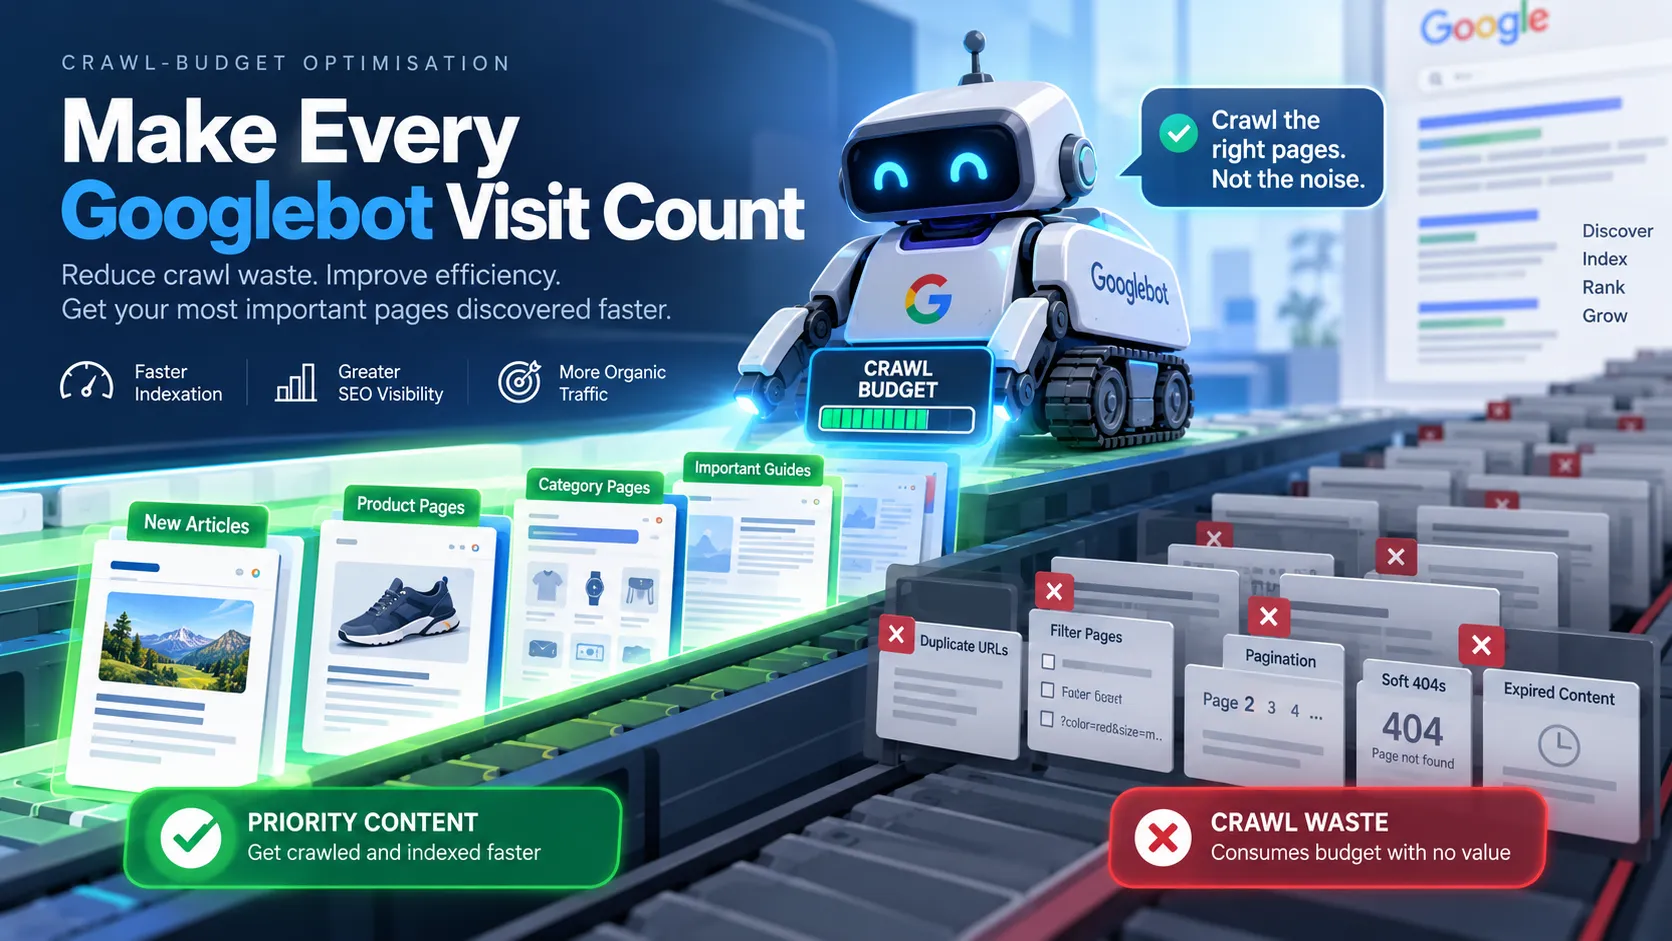
Crawl budget sounds abstract, but its impact is concrete. A product page launched on Monday might not appear in Google Search until the following week, not because of quality issues, but because Googlebot never reached it. Meanwhile, your site wasted crawl allocation on duplicate filter pages, pagination archives, and soft 404s that served no one.
In documented cases, we have seen delays of one to two weeks before newly published content enters the index. Results vary by site size and structure. Unlike many SEO problems that take months to resolve, crawl-budget optimisation can deliver measurable results in just weeks. Reclaim wasted allocation, and newly published content enters the index faster. Fix server speed, and Googlebot crawls more pages per day. Remove low-value URLs from your sitemap, and priority content gets discovered sooner.
The challenge is visibility. Google does not flag crawl waste directly. Audit it, understand its source, and take steps to address it.
Key Takeaways
- Google allocates crawl budget daily and refreshes it over time based on authority and speed signals. Google assigns a limited number of page crawls to your site based on domain authority, server speed, and content freshness. Wasting this budget on low-value URLs delays discovery of priority content.
- Crawl budget and index budget are separate. A page can be crawled but not indexed if it has a noindex tag, duplicate content, or soft 404 responses. Optimising crawl efficiency is pointless if crawled pages then fail to index.
- The top waste patterns on most sites are faceted navigation (parameter-heavy URLs), deep pagination, slow server response times, and redirect chains. You can identify these for free in Google Search Console. Fixing them can accelerate content discovery by days to weeks.
- Server response time (Time to First Byte, or TTFB) directly constrains crawl budget. A page that takes 5 seconds to load consumes budget faster than a page that loads in 0.5 seconds.
- You cannot request a larger crawl budget from Google, but you can reclaim wasted budget by removing non-essential URLs from your sitemap, blocking low-value paths in robots.txt, and consolidating duplicate content with canonical tags.
- Consistency patterns in crawl volume vary by content type, site age, and update frequency. Sites with under 10,000 pages typically receive a sufficient crawl budget to be fully crawled multiple times per month, provided hosting is reasonable. The constraint appears at scale (100,000+ pages) or with slow servers.
- Monitor crawl health monthly via Google Search Console’s Coverage report and Crawl Statistics. Track your crawl efficiency ratio (URLs crawled per day divided by budget URLs) to catch problems early.
What Is Crawl Budget and Why It Matters for SEO
Crawl budget is the number of URLs Google will crawl on your site within a given timeframe, typically measured as pages per day. Crawl budget functions as a resource allocation determined by site-level signals. Google assigns a specific quota of crawler capacity to your domain based on several factors. When that quota is exhausted, Googlebot stops crawling and returns the next day.
This constraint matters because the crawl budget is finite. Google’s crawler is shared infrastructure serving the entire web. Your allocation depends on three variables: your site’s perceived authority (reflected in factors like domain authority and backlink profile), your server’s response speed, and how often your site updates with fresh content. A high-authority site on fast servers gets more daily crawl budget. A new site, or one hosted on sluggish shared servers, will receive less.
Sites often waste crawl budget on pages that deliver zero search visibility. A typical scenario: you launch 50 new product pages on Monday, but your crawl budget is fully consumed by crawling pagination links, old archive pages, and duplicate filter combinations. Googlebot does not discover your new products until the following week or later. In competitive verticals (e-commerce, SaaS, job boards), this delay translates to missed ranking opportunities and lost organic traffic.
A documented pattern in e-commerce audits shows that sites often waste budget on pagination pages consumed by low-value filter combinations. Investigation of such cases revealed that a significant portion of daily crawl budget was spent on pagination pages (/products?page=2, /products?page=3, and so on) and filter combinations that served no search intent. The same budget, refocused, would have discovered new products within 48 hours.
Crawl Budget vs. Index Budget: The Critical Difference
Crawl budget and index budget are sequential gates, not the same thing. Understanding the distinction is essential because they can fail independently.
Crawl budget: the decision to crawl a URL. Googlebot evaluates whether a page is worth fetching based on your site’s authority, server speed, and freshness signals.
Index budget: the decision to add a crawled page to Google’s index. After Googlebot fetches a page, Google decides whether it is unique and valuable enough to store. Duplicate content, noindex tags, soft 404 responses, and thin pages fail the index-budget gate even if Google crawls them.
Here is why this issue matters: optimising crawl budget alone is insufficient. A site might ensure all 10,000 product pages are crawled, only to discover that 9,000 have been removed from the index because of canonicalisation errors or noindex tags.
Consider this scenario: a clothing retailer’s site has /products/shirt-red-s, /products/shirt-red-m, and /products/shirt-red-l as separate URLs. Googlebot crawls all three, spending the crawl budget. But the site implements a canonical tag pointing all three to /products/shirt-red (index budget decision). Only the canonical URL enters the index. The crawl budget was wasted on pages that provide no search visibility.
This separation also explains why a page can disappear from search results even though Googlebot continues crawling it. The page was crawled and indexed once, but then a noindex tag was added or a canonicalisation error introduced. The page is still being crawled (resources spent), but the index budget now rejects it.
Why a Finite Crawl Budget Exists
Google’s Googlebot is a shared crawler serving billions of web pages. The company has finite computing resources and infrastructure costs. Rather than crawl the entire web simultaneously, Google prioritises based on site-level signals.
Your crawl allocation increases if:
- Your site has high domain authority (earned through quality backlinks).
- Your server responds quickly. A page taking 5 seconds to load consumes five times more infrastructure than a page loading in 1 second, reducing the number of pages Googlebot can crawl in your budget window.
- Your site updates frequently. A news site or e-commerce platform with daily changes receives higher crawl frequency than a static blog updated quarterly.
Your crawl allocation decreases if:
- Your server is slow (Time to First Byte, or TTFB). A sluggish shared hosting environment or an unoptimised WordPress installation will immediately constrain your budget.
- Your site has low authority or is new. A startup e-commerce site receives minimal budget until it builds backlinks and domain trust.
- Your site contains excessive duplicate content. If 50% of your pages are near-duplicates, Google allocates less budget because the marginal value of crawling additional pages is low.
Many WordPress sites operate on shared hosting with TTFB between 800ms and 2000ms. Compare the performance to a site on optimised managed hosting delivering TTFB under 200ms. The latter site typically receives a higher crawl budget per day for the same authority level, simply because Googlebot can fetch more pages per second.
Here is the practical result: a slow site exhausts its budget without crawling all priority content. A fast site reaches deeper into its crawlable pages and discovers new URLs sooner.
How to Audit Your Current Crawl Budget Usage
Identifying where your crawl budget goes is the foundation of fixing it. Most sites waste their budget without knowing where it goes. This section walks you through a four-step diagnostic framework that uses tools available to most SEO teams, from free Google Search Console features to specialised log-file analysers.
Step 1: Analyse Crawl Stats in Google Search Console
Google Search Console is your first lens into Googlebot’s behaviour on your site.
Log in to Google Search Console and navigate to Settings > Crawl Statistics. This view shows the previous 90 days of Googlebot activity. Download the CSV to work with the raw data. The report includes:
- URLs crawled per day: How many pages Googlebot visited that day
- Kilobytes downloaded: The total data volume fetched
- Crawl time (seconds per page): Average time Googlebot spent loading each page
Look for patterns. Consistency patterns vary by content type, site age, and update frequency. A spike in crawl time without a corresponding rise in URLs crawled per day signals inefficiency: Googlebot is slower, so it covers fewer pages within its budget.
For example, if your average crawl time jumps from 0.5 seconds per page to 2.5 seconds per page and the number of URLs crawled per day drops from 500 to 200, your server has slowed down. This issue is often caused by unoptimised plugins, database queries, or third-party scripts loading during page render. Result: content discovery may be delayed by 7–10 days.
Export 90 days of data and chart the URLs crawled and the average crawl time on a timeline. Look for downward or upward trends that correlate with changes you made: new plugin, server migration, or content refresh.
Step 2: Identify Pages Crawled but Not Indexed
Google Search Console’s Coverage report reveals a critical inefficiency: pages consume your crawl budget but deliver zero search visibility because they aren’t indexed.
Navigate to Coverage. Expand the “Excluded” section and filter specifically for “Crawled, currently not indexed. This is the waste list. Export it as a CSV.
Common culprits include:
- Pagination pages: /products/page/2, /blog/page/3. They are crawled; they are not indexed
- Thank-you pages: Post-form confirmation pages that should never rank
- Internal search results: /search?q=shoes&sort=price, where each search query spawns a unique URL
- Parameter-heavy e-commerce URLs: /products?sort=price&colour=red&size=M&brand=Nike, where filter combinations create thousands of thin variations
- Session-based URLs: Sites that append session IDs (?sessionid=abc123) to every link
These pages consume crawl budget in real time. If you have 2,000 “crawled but not indexed” pages and Googlebot crawls only 500 URLs per day, you’re spending 4 days of budget on pages that will never rank.
Filter the Coverage report for “Crawled, currently not indexed.” Count them. If the number exceeds 10% of your total crawled URLs, investigate. Take a random sample of 20 pages from that list and identify the pattern.
Step 3: Use Log-File Analysis for Depth
Google Search Console gives you the aggregate picture. Log-file analysis shows exactly which URLs Googlebot touched, when, and for how long.
Search Console aggregates data. It does not tell you if one URL was crawled 50 times in a day or if another was not crawled at all despite needing to be. Log-file analysis tools parse your server access logs (typically stored in /var/log/apache2/ or /var/log/nginx/ on Linux servers, or via your hosting control panel).
Recommended tools for this audit:
- Screaming Frog (paid desktop application): Import your server logs via “Log File Importer”. It shows every Googlebot request with HTTP status, response time, and crawl frequency per URL
- Botify (cloud-based SaaS): Purpose-built for crawl analysis; integrates with Google Analytics and Google Search Console. Popular with enterprise e-commerce and SaaS teams
- Digimetrics.ai: Crawls your live site up to 500 URLs without log-file import; adequate for smaller audits
A documented pattern in e-commerce audits reveals how pagination consumes disproportionate budget on low-value filter combinations. Log-file analysis shows when Googlebot visited a URL 500 times in one day because of a redirect loop or misconfigured pagination. That is wasted budget on a single URL.
Please obtain your server access logs from the past 30 days. Most hosting providers (SiteGround, Kinsta, AWS, and DigitalOcean) provide log downloads via the control panel or SSH access. If you use Cloudflare, enable Web Analytics for a similar view. Import logs into Screaming Frog or Botify. Filter for Googlebot user-agent requests. Sort by “Crawl Frequency” in descending order. Any URL crawled more than once per day (unless it is the homepage or a sitemap) warrants investigation.
Step 4: Check for Redirect Chains and Loops
Redirects are necessary for URL migrations, HTTPS upgrades, and moving pages. Chains and loops waste your budget.
A redirect chain: URL A (301) → URL B (301) → URL C (final destination). Googlebot must follow all three hops. A loop: URL A → URL B → URL A. Googlebot can get stuck.
Export your XML sitemap(s). Most content management systems allow you to download from /sitemap.xml or the admin panel. Export the list of URLs Googlebot crawled from the log-file analysis above or from Google Search Console. Use a bulk redirect checker tool.
Screaming Frog’s “Redirect Chain” report shows redirect paths visually when you crawl your site. Ahrefs and SEMrush also offer crawl-audit features that visualise redirect chains.
Look for patterns:
- Are redirects longer than two hops (e.g., A → B → C → D)?
- Do any URLs redirect in a circle (e.g., A → B → A)?
- Are redirects pointing to pages that themselves redirect (indirect chain)?
A single two-hop chain costs little. Thousands of one-hop chains across a site add up. If your site underwent a URL structure overhaul and you did not fully migrate old URLs, redirect chains will accumulate.
Use Screaming Frog to crawl your site. Export the report and filter it for “Redirect Chains”. If you find any chains with 3 or more hops, prioritise updating them to point directly to the final destination. Update any internal links pointing to the intermediate URLs.
Diagnostic Summary Table
| Audit Step | Tool/Method | Red Flag | Action |
|---|---|---|---|
| Crawl Stats | Google Search Console Settings > Crawl Statistics | Crawl time rising without crawled URLs rising | Optimise server response time; check for new plugins or third-party scripts |
| Crawl vs. Index | Google Search Console Coverage report | More than 10% of crawled URLs not indexed | Audit and block pagination, filters, and session URLs |
| Log-File Analysis | Screaming Frog, Botify | URLs crawled 50+ times per day | Check for redirect loops; fix pagination; add nofollow to repeated parameters |
| Redirect Chains | Screaming Frog or online checker | 3+ hop chains; circular redirects | Update internal links; point old URLs directly to the final destination |
These four steps pinpoint where your budget is leaking. Sites often waste crawl budget on pages that deliver zero search visibility. Once you have identified the waste, the next section shows you how to reclaim it.
Common Crawl-Budget Waste Patterns and How to Spot Them
Most sites waste crawl budget without identifying where the drain is. The patterns below account for most budget loss across e-commerce, publishing, and content-heavy platforms.
E-commerce sites often generate infinite URL variations through filters. A shoe store might create /shoes?brand=Nike&colour=Black&size=10&price=50-100. Each additional filter multiplies the URL count exponentially. Googlebot treats every variation as a unique page, even though the product content is nearly identical.
The problem: Googlebot crawls every variation, consuming budget on pages that rarely rank independently and rarely drive conversions. A site with 500 products and 8 filter combinations per product generates 4,000 crawlable URLs instead of just 500. This can delay priority content discovery by one to two weeks.
To identify parameter bloat, log into Google Search Console. Navigate to Coverage. Filter for “Crawled, currently not indexed. If you see dozens of URLs with identical or near-identical query parameters (differing only in filter values), parameter bloat is consuming your budget.
Solutions:
- Use rel=”canonical” to consolidate filter combinations to the base product or unfiltered category page. Point all variations to the canonical product URL
- Block filter combinations in robots.txt using patterns like Disallow: /*?*colour= (blocks all URLs with a colour parameter)
- Use rel=”nofollow” on filter links to prevent Googlebot from following them
Consolidating via canonical is most effective. This maintains the filter page experience for users while signalling to Googlebot that it should prioritise the canonical.
Pagination Without Proper Signals
Archive pages, category pages, and blog listing pages generate sequences of URLs: /page/2, /page/3, /page/10, and so on. Without explicit signals, Googlebot treats each page as a unique destination and crawls all of them. Page 10 of a blog archive rarely contains indexable content that has SEO value. Fewer than 1% of users scroll past page 3. Yet Googlebot spends its crawl budget on pages that will never drive traffic.
In Search Console Coverage, look for “Crawled, currently not indexed” pages with patterns like /blog/page/8/ or /products/category/page/15/. Use log-file analysis tools to see exactly how often pages beyond page 3 are being crawled.
Solutions:
- Implement rel=”next” and rel=”prev” tags on paginated pages. This tells Googlebot that pages form a sequence and consolidates crawl signals to the first page
- Add rel=”nofollow” to links pointing to pages beyond page 2 in your pagination component. Let internal linking drive discovery of page 2 only
- Link to pagination pages only from the homepage or category page, not from other parts of the site. Reduce the entry points
For older content (archives from two or more years ago), block deeper pages entirely with robots.txt: Disallow: /blog/page/[5-9]/ or Disallow: /blog/page/[0-9]{2,}/ (blocks pages 10 and above).
Outdated or Duplicate Content Still Crawlable
Seasonal content, old blog posts, product listings for discontinued SKUs, and duplicate pages often remain on the server and visible to Googlebot. They are not deleted; they are simply unmarketed and unlinked. Yet Googlebot still crawls them because they remain reachable via XML sitemap, internal links from archive pages, or external backlinks.
Sites often waste crawl budget on pages that deliver zero search visibility. If you have three ways to view the same product (for example, /products/shoes/nike-air-max, /products/nike-air-max, and /nike-air-max), Google splits the crawl budget across all three when it should focus on just one.
How to spot it:
- Export your XML sitemap and identify pages last modified over 12 months ago
- Check your Search Console Coverage report for pages with low traffic or no clicks, yet still crawled regularly
- Run a content audit. List every page on your site and categorise it as “live and marketed”, “live but archived”, or “duplicate”. Pages in the second and third categories are budget waste
Solutions:
- For truly archived content (for example, past event pages, seasonal promotions), return a 410 (Gone) HTTP status code instead of 200. This tells Googlebot the page is intentionally removed and stops it from crawling it
- For content you want to keep but not index (for example, internal documentation), add <meta name=”robots” content=”noindex”> to the page header. Googlebot crawls it but does not index it, freeing budget for priority pages
- For duplicate content you are keeping, canonicalise it. Use <link rel=”canonical” href=”https://example.com/canonical-url/”> to point all variations to a single master version
- Remove outdated content from your XML sitemap entirely.
Use this threshold: if a page has not been updated in 18 months and drives fewer than 5 monthly visits, it is a candidate for removal or noindexing.
Slow Pages Eating Disproportionate Budget
Googlebot allocates a fixed time budget to each site each day. If a page takes 5 seconds to load, Googlebot crawls only 12 pages per minute instead of 60. Across an 8-hour crawl window, a slow site crawls approximately 5,760 pages instead of 28,800 pages, a significant loss.
Server-side rendering without optimisation, unminified JavaScript, unoptimised images, and third-party scripts (analytics, ads, chat widgets) commonly cause delays.
How to spot it:
- In Google Search Console, navigate to Settings and select Crawl Statistics. Download the CSV. If average crawl time per page exceeds 2 seconds, page speed is the limiting factor
- Use <a href=”https://pagespeed.web.dev”>Google PageSpeed Insights</a> or WebPageTest to measure Time to First Byte (TTFB). Google targets under 200ms. Anything above 500 ms is critical
- Check response times in your server logs. A spike in 200-level responses with high response times signals server strain
Solutions:
- Upgrade hosting or use a content delivery network (CDN). A CDN serving from local points of presence can reduce TTFB for regional users; results depend on configuration
- Defer non-critical JavaScript. Move analytics, ads, and chat widgets to async loading so they do not block page rendering.
- Optimise images using modern formats (WebP) and compression. Use responsive images with srcset attributes
- Implement a caching layer (Redis, Memcached) for database queries
- Enable Gzip compression on the server
Check TTFB right now. If it exceeds 300ms, prioritising this change will recover more crawl budget than any other single change.
Excessive Redirects and 404s
Every time Googlebot encounters a 301 or 302 redirect, it consumes crawl budget to follow the chain. If the destination is another redirect, Googlebot follows that too. A chain of three redirects means three crawl requests for a single piece of content.
404 errors are equally wasteful. A URL that returns a 404 status consumes budget but delivers no indexable content. Broken internal links, old URL structures that were not fully migrated, and typos in sitemaps all generate 404s that accumulate.
How to spot it:
- In Search Console, navigate to Coverage. Look for “Crawled, currently not indexed.” Filter by 404 responses
- Use log-file analysis tools to identify chains. These tools visualise redirect chains when you import your server logs
- Manually crawl your site with a third-party crawler and review the Redirect Chain report. Any chain longer than one hop is worth investigating
Solutions:
- Replace redirect chains with direct redirects. If /old-page redirects to /intermediate, and /intermediate redirects to /new-page, replace the first redirect to point directly to /new-page
- Remove broken links from your navigation, footer, and internal content. Use a crawler to identify links returning 404s
- If a URL is truly gone and will not return, respond with a 410 (Gone) status instead of 404. Googlebot will stop requesting it sooner
- Audit your sitemap for URLs that no longer exist. Remove them
Redirect chains and 404s are low-hanging fruit. Fixing the top 50 often recovers 5–10% of your crawl budget immediately.
Strategies to Reclaim and Optimise Crawl Budget
Move from diagnosis to action. The following five strategies are sequenced by impact and ease of implementation. Start with Strategy 1 (sitemap pruning), which requires no server changes and delivers immediate results.
Strategy 1: Prioritise Your Sitemap
Your XML sitemap is the primary signal you send to Googlebot about which URLs deserve crawling. Every URL in your sitemap consumes part of your daily crawl budget. Removing low-value URLs is the fastest way to redirect budget toward pages that matter.
Please audit your current sitemap as soon as possible. Export it and remove:
- Pagination pages (/products?page=2, /blog/page/3/)
- Parameter combinations that create near-duplicates (/shoes?colour=red&size=10&price=50-100)
- Admin, staging, and internal-only URLs
- 404 pages and archived content
- Duplicate versions (HTTP and HTTPS both listed, or www and non-www variants)
A site with 50,000 URLs in its sitemap but only 5,000 unique, indexable pages wastes resources. Googlebot spends crawl requests on noise instead of priority content.
For large sites, segment your sitemap. Rather than one monolithic file, create separate sitemaps: one for products, one for blog posts, and one for category pages. This lets you update each independently and tell Googlebot which sitemaps carry your highest-priority content.
In your robots.txt, reference sitemaps in order of importance:
Sitemap: https://example.com/sitemap-products.xml
Sitemap: https://example.com/sitemap-blog.xml
Sitemap: https://example.com/sitemap-categories.xml
Googlebot treats the first sitemap as primary and allocates more budget to it. E-commerce sites should list product sitemaps first; publishing sites should list newest-content sitemaps first.
Review your sitemap monthly. URLs that no longer exist, have been merged, or now carry noindex tags should be removed. A stale sitemap tells Googlebot to revisit pages it shouldn’t, wasting budget on every visit.
Strategy 2: Fix Server Speed Before Adjusting Crawl Rate
In Google Search Console, you can adjust the crawl rate under Settings > Crawl Rate. This setting tells Googlebot to pause between requests. Slowing Googlebot down can improve efficiency if your server is struggling under load. Instead of timing out on slow pages, Googlebot completes more crawls successfully.
However, this method is a last resort, not a primary fix.
Only use crawl-rate reduction if you see this pattern: Your server response time (Time to First Byte, or TTFB) is consistently above 500ms, and crawling spikes correlate with server performance degradation. Reducing crawl rate prevents overload while you fix the underlying problem.
The better approach: improve server speed first. Aim for TTFB under 200ms. A speedy server automatically increases the number of pages Googlebot can crawl per day without configuration changes.
Regional CDNs (networks of servers distributed by geography) can deliver rapid wins. Cloudflare, AWS CloudFront, and Akamai maintain nodes across Asia-Pacific. Routing content through a regional CDN can significantly reduce TTFB. Results depend on configuration and your origin server location. The cost, typically USD 20–100 per month for small sites, is modest compared to the crawl-budget recovery.
Once TTFB improves, reset the crawl rate to its default. Googlebot will automatically crawl faster, and you’ve solved the problem without limiting content discovery.
Strategy 3: Use robots.txt Strategically
robots.txt blocks crawling; it does not prevent indexing. A URL blocked in robots.txt can still be indexed if another site links to it. Use it to hide directories Googlebot does not need to crawl.
Safe directories to block:
- /admin/ (administrative interface)
- /staging/ (development environment)
- /internal-search/ (site search results, which are parameter-driven and vary by user input)
- /user-profiles/ (if publicly accessible but low-value)
- /api/ (if not needed for rendering pages)
- /checkout/ (transactional pages with no SEO value)
Critical mistake: do not block static resources. Many WordPress sites mistakenly block /wp-admin/. This catches subdirectories like /wp-admin/includes/ which serve CSS, JavaScript, and template files. Googlebot needs these files to render pages. Block only the specific admin interface:
Disallow: /wp-admin/
Allow: /wp-admin/includes/
Alternatively, you can use a crawl-delay instead of a blanket block.
Review your robots.txt weekly. It’s easy to add a rule and forget it. Over time, blocked directories accumulate and unnecessarily limit Googlebot’s access. If a directory is truly not needed, delete it or use a 410 (Gone) HTTP response instead of robots.txt.
Strategy 4: Consolidate Duplicate and Near-Duplicate Content
Multiple URLs serving the same or nearly identical content force Googlebot to choose which one to crawl. Without clear signals, Googlebot crawls all of them.
Common duplication sources:
- HTTP and HTTPS versions are both accessible
- www and non-www variants
- Mobile and desktop versions on separate URLs (m.example.com and example.com)
- Parameter variations (?sort=price, ?sort=rating, ?view=grid, ?view=list)
- Trailing slash variants (/products and /products/)
Use rel=”canonical” in the <head> of each duplicate to point Googlebot to the authoritative version:
<link rel=”canonical” href=”https://example.com/products/shoes/” />
For e-commerce, canonicalise product variations to the parent product. E-commerce sites often waste budget on pagination consumed by low-value filter combinations. If you sell a shoe in multiple sizes and colours, consolidate them:
/products/nike-air-max-black-size-10 → /products/nike-air-max (canonical)
/products/nike-air-max-black-size-11 → /products/nike-air-max (canonical)
Googlebot crawls the canonical URL once and learns it represents multiple variants. Budget spent on variants drops dramatically.
Test your canonicals. Use Google Search Console’s URL Inspection tool. Paste a URL and check if Google sees the correct canonical. If it shows the wrong canonical, please address it as soon as possible.
Strategy 5: Optimise Internal Link Structure
Googlebot discovers pages by following links. Deep nesting forces Googlebot to follow many hops to reach priority pages, wasting budget on intermediate pages along the way.
Measure click depth: count the minimum number of clicks needed from the homepage to reach each URL. Priority pages (product pages, top blog posts, and service pages) should be reachable in 2–3 clicks maximum. Pages beyond 5 clicks are infrequently crawled.
Restructure your navigation. If category pages are buried 4 clicks deep, add breadcrumb navigation or homepage shortcuts. Internal linking is free; use it strategically.
Add contextual internal links. Links within body copy carry more weight than navigation links alone. From high-authority pages (homepage, popular blog posts), link directly to pages you want crawled more frequently:
We recommend this new product page (e.g. abc.com/item/new-product-page) for customers seeking X functionality.
Googlebot sees the link and prioritises the new page. It discovers the page faster and assigns more crawl visits.
Remove link orphans. Pages with no internal links are difficult for Googlebot to find. Audit your site structure: every page should be reachable from the homepage within 3 clicks. A page with zero internal links delays content discovery.
These five strategies work together. Prune your sitemap first (Strategy 1). This cuts waste immediately. While optimising, also fix server speed (Strategy 2). Then apply robots.txt rules (Strategy 3) to block directories that slow crawling. Consolidate duplicates (Strategy 4), so Googlebot doesn’t repeat work. Finally, restructure internal links (Strategy 5) so the budget you’ve freed up flows toward priority content. Together, these moves can deliver measurable results within weeks, though outcomes vary by site size and architecture.
Crawl-Budget Optimisation for Different Site Architectures
Different site types have different priorities. Tailor the approach to your architecture.
Large E-Commerce Sites
E-commerce sites often have 100,000+ SKUs. Crawl budget is the bottleneck.
In documented cases, e-commerce sites have experienced content discovery delays of one to two weeks when they exhausted their crawl budget on product variations. A fashion retailer with 50,000 product variations (the same shirt in 10 colours and 8 sizes) can exhaust its daily crawl budget on size and colour combinations, leaving new inventory undiscovered for extended periods. Googlebot crawls variant URLs as separate pages. Each represents a duplicate with marginal SEO value.
Canonicalise product variations
Consolidate by colour, size, material, or other attributes into a single master product URL. If you sell a t-shirt in navy, black, and white, use one canonical product page and let filters show options. Point all variant URLs to the master canonical:
<link rel=”canonical” href=”https://example.com/products/navy-t-shirt” />
This tells Googlebot to crawl the master page and ignore the variants. You keep variants live for user navigation and conversion while stopping wasted crawl budget.
Limit pagination depth
Category pages auto-generate pagination: /shoes/page/1, /shoes/page/2, up to /shoes/page/47. Googlebot crawls all by default. Pages 20+ have negligible traffic and SEO value.
Link to page 2 from the homepage. Use rel=”next” and rel=”prev” tags only on pages 1 and 2. For page 3 onwards, omit these tags, which signal to Googlebot that the series ends. Alternatively, block pages 3+ in your robots.txt:
Disallow: /shoes/page/[3-9]
Disallow: /shoes/page/[0-9]{2,}
This saves thousands of crawls per month on a large site.
Block filters
E-commerce filters create URL explosions. A category with 5 brand options, 8 colours, and 6 price ranges generates 240 unique filter combinations. If each is indexed separately, Googlebot spends requests on thin-value pages.
In robots.txt, block parameter-driven filter combinations:
Disallow: /*?*brand=
Disallow: /*?*colour=
Disallow: /*?*price=
This tells Googlebot not to crawl URLs containing these parameters. Users can still access filters through internal navigation, but Googlebot wastes no budget on them.
Manage inventory updates selectively
E-commerce inventory changes constantly. Rather than updating your sitemap every time a product goes out of stock, batch updates. Update your product sitemap once per week, not hourly. This reduces unnecessary re-crawls and lets Googlebot focus on genuinely new products.
Use the lastmod tag in your sitemap to signal which pages changed. Googlebot prioritises pages with recent lastmod dates, so use this field only for genuinely updated products, not for every update cycle.
Content-Heavy Publishing Sites
News outlets, magazines, and blogs publish dozens of articles daily and maintain archives spanning years. Crawl budget determines whether Google indexes new content before it becomes stale and whether it revisits deep archive content.
Consistency patterns vary by content type, site age, and update frequency. A healthy publishing site typically shows regular crawl activity, but patterns differ between daily news publishers and monthly journals.
Prioritise new content in your sitemap.
Create a separate “news” or “recent” sitemap containing only articles from the past 30 days. Reference this in robots.txt as your first sitemap:
Sitemap: https://example.com/sitemap-news-recent.xml
Sitemap: https://example.com/sitemap-archive.xml
Googlebot crawls the recent-content sitemap first, ensuring it discovers new articles within hours. Archive content is crawled second, using remaining budget.
Use Noindex on Archive Pagination
Publishing sites often generate hundreds or thousands of paginated archive URLs:
/blog/page/2/
/blog/page/3/
/blog/page/50/
These pages help users browse older content, but they rarely deserve to appear independently in search results.
If every archive page remains indexable, Googlebot may repeatedly crawl them even though most deliver little unique search value.
Add a noindex directive to deeper archive pages while keeping the main archive or category page indexable:
<meta name="robots" content="noindex, follow">
The follow instruction allows Googlebot to continue discovering article links from the archive while preventing the archive page itself from entering the index.
A practical structure might look like this:
/news/ → Index
/news/page/2/ → Noindex, follow
/news/page/3/ → Noindex, follow
This reduces index clutter while preserving crawl paths to older articles.
Be careful not to remove pagination links entirely. If archive pagination is the only way Googlebot can reach older content, removing those links can create orphaned pages.
The objective is to prevent low-value archive pages from entering the index while still allowing Googlebot to discover the articles behind them.
Strengthen Internal Links to Priority Articles
Publishing sites often focus heavily on publishing frequency and not enough on internal linking.
A new article might appear on the homepage for two days, then disappear into an archive where Googlebot visits less frequently.
Prevent this by linking new strategic articles from older, high-authority pages.
If you publish an important guide on crawl-budget optimisation, add contextual links from existing SEO articles that already receive traffic.
For example:
“If your site contains thousands of URLs, you should also review your crawl-budget optimisation strategy.”
This tells Googlebot that the new article is important and gives it multiple discovery paths.
Prioritise internal links from:
- Homepage
- High-traffic articles
- Category landing pages
- Evergreen guides
- Frequently crawled resource pages
The stronger the internal-link network around a page, the easier it is for Googlebot to discover and revisit it.
For news publishers, this is especially important because content freshness matters. A breaking article that takes two days to be discovered may already have lost much of its commercial value.
Remove Obsolete Archives from Crawl Paths
Publishing sites accumulate years of content.
Some old content still earns traffic and links. Other pages have not received a visit in years and contain outdated information.
Don’t delete everything just because it is old. Age alone is not the problem. Crawl value is.
Audit articles using three signals:
- Organic traffic
- Backlinks
- Current relevance
For example:
Old article:
SEO Trends for 2019
Current article:
SEO Trends for 2026
If the older article has no meaningful backlinks, redirect it to the newer version.
If it contains unique historical value, update it and retain it.
If it has no value at all, remove it and return an appropriate HTTP status.
This keeps Googlebot focused on content that still matters.
Use Lastmod Accurately
Publishing sites frequently misuse the <lastmod> field in XML sitemaps.
Some CMS platforms automatically update the last modified date every time a plugin changes metadata, a template is updated, or another minor technical change occurs.
This can make thousands of pages appear freshly updated even when nothing meaningful changed.
As a result, Googlebot may revisit content that has not substantially changed.
Only update <lastmod> when visible page content materially changes.
Good reasons to update it include:
- Major factual updates
- New sections added
- Updated statistics
- Significant content rewrites
- Product or pricing changes
Do not update it simply because:
- A plugin updated
- The footer changed
- An advertisement refreshed
- Minor formatting changed
- Analytics code changed
A trustworthy sitemap improves crawl efficiency because Google learns that your freshness signals are meaningful.
SaaS and Software Platforms
SaaS websites face a different crawl-budget problem.
They often contain public marketing pages alongside thousands of internal application URLs, documentation pages, parameter-driven reports, user profiles, and automatically generated states.
The challenge is separating pages intended for search from pages intended only for users.
1. Block Application Interfaces from Crawling
Most SaaS application screens should never be crawled.
Examples include:
/dashboard/
/account/
/settings/
/reports/
/projects/
/billing/
/login/
These pages have no search value and often require authentication anyway.
Where appropriate, prevent Googlebot from crawling unnecessary application areas using controls such as authentication or robots.txt.
For example:
Disallow: /dashboard/
Disallow: /account/
Disallow: /settings/
Disallow: /reports/
Do not waste crawl resources allowing Googlebot to explore private product interfaces.
Keep your crawlable site focused on:
- Product pages
- Feature pages
- Use-case pages
- Blog content
- Documentation
- Comparison pages
- Templates
- Public tools
The goal is to create a clear boundary between your marketing website and your application.
2. Control Generated URLs
SaaS platforms frequently generate URLs dynamically.
For example:
/reports?id=123
/reports?id=124
/reports?id=125
If these URLs are publicly accessible, Googlebot may discover thousands of variations.
Use one or more of the following controls:
- Authentication
robots.txtnoindex- Canonical tags
- Sitemap exclusions
Authentication is usually strongest for genuinely private pages because inaccessible pages cannot be crawled normally.
If pages must remain publicly accessible, make sure they are excluded from XML sitemaps when they have no search value.
3. Prioritise Feature and Solution Pages
Commercial SaaS pages should sit close to the homepage.
A strong hierarchy might look like:
Homepage
→ Features
→ SEO Audit Tool
→ Crawl Analysis Tool
Or:
Homepage
→ Solutions
→ Agencies
→ Enterprise SEO
Avoid burying important commercial pages five or six clicks deep beneath navigation layers.
Priority pages should generally be reachable within two to three clicks from the homepage.
Commercial pages that generate revenue deserve prominent internal links and clear crawl paths.
4. Manage Documentation Carefully
Technical documentation can generate thousands of URLs.
Some documentation pages rank extremely well because they answer specific technical questions.
Others are obsolete version pages that consume crawl resources unnecessarily.
For example:
/docs/v1/
/docs/v2/
/docs/v3/
If version 1 is no longer supported, decide whether users genuinely need those pages.
If not:
- Redirect old documentation to the current equivalent
- Noindex obsolete pages where appropriate
- Remove outdated URLs from the sitemap
- Remove pages that no longer serve users
Do not allow Googlebot to spend excessive time crawling documentation for products or versions that users can no longer use.
Job Boards and Marketplace Sites
Job boards, property portals, classified sites, and marketplaces face some of the largest crawl-budget challenges on the web.
Their inventory changes constantly.
Listings appear and disappear every day, while filters can generate millions of possible URLs.
1. Remove Expired Listings Quickly
An expired job or property listing should not remain crawlable indefinitely without a clear purpose.
If the listing has a relevant replacement, redirect users to the most appropriate broader category page.
For example:
Expired:
/jobs/senior-seo-manager-company-x
Relevant destination:
/jobs/seo/
If there is no meaningful replacement, remove the page appropriately.
Do not leave millions of expired listings returning a normal 200 status while displaying only:
“This position is no longer available.”
These pages can become soft 404s.
Googlebot may continue crawling them because technically the URLs still exist.
At scale, expired inventory can consume a substantial proportion of crawl resources.
2. Control Location and Filter Combinations
Marketplace filters create combinatorial URL growth.
A property portal might allow:
Location × Price × Bedrooms × Property Type × Tenure
Ten locations × ten price ranges × five bedroom options × five property types already creates 2,500 combinations.
Add more filters and the number becomes enormous.
Only allow Googlebot to crawl combinations with genuine search demand.
For example:
/condos-singapore/
/condos-orchard/
/2-bedroom-condos-orchard/
These may represent real search queries.
But a URL such as:
/condos?bedrooms=2&floor=high&pool=yes&parking=yes&sort=newest
probably does not need independent indexation.
Use canonical tags, robots controls, internal-link rules, and noindex directives where appropriate to control these combinations.
3. Prioritise Fresh Inventory
Job boards and marketplaces depend heavily on freshness.
Googlebot should spend more of its crawling activity on new and active listings than on expired ones.
Create separate XML sitemaps such as:
sitemap-new-jobs.xml
sitemap-active-jobs.xml
sitemap-categories.xml
Update the newest-listings sitemap frequently.
Remove expired listings promptly.
This helps search engines distinguish fresh inventory from older or inactive content.
4. Keep Category Pages Permanent
Individual listings come and go.
Category pages remain.
That makes category pages strategically important.
A page such as:
/jobs/digital-marketing/
should remain permanent even when individual vacancies change.
Optimise category pages with:
- Introductory copy
- Internal links
- Related roles
- Location filters
- Salary information
- Frequently asked questions
This gives Google a stable URL to rank while short-lived listings appear and disappear beneath it.
How to Measure Whether Crawl-Budget Optimisation Is Working
Crawl-budget optimisation should produce measurable changes.
Do not judge success purely by whether Search Console reports more crawling.
More crawling is useful only if Googlebot is crawling the right pages.
Track the following five metrics.
1. URLs Crawled Per Day
Measure this in Google Search Console under Crawl Statistics.
After optimisation, the number may increase because your server is faster.
But an increase is not automatically good.
Compare crawl volume against the types of URLs being crawled.
If Googlebot is crawling more priority pages and fewer parameter URLs, the change is positive.
2. Average Crawl Response Time
Track average response time over time.
If it drops substantially, Googlebot can potentially request more pages within the same period.
For large websites, server-speed improvements can create some of the biggest crawl-efficiency gains.
Monitor server performance alongside crawl activity so you can see whether faster responses correspond with improved crawling.
3. Percentage of Crawled URLs That Are Valuable
Create a simple internal efficiency metric:
Crawl Efficiency Ratio = Priority URLs Crawled ÷ Total URLs Crawled
Example:
Googlebot crawled 10,000 URLs.
7,500 were priority pages.
Crawl efficiency:
7,500 ÷ 10,000 = 75%
If only 4,000 were priority pages, your efficiency would be 40%.
Track this monthly.
Your objective is not necessarily 100%. Googlebot will naturally encounter redirects, old URLs, duplicates, and other non-priority pages.
The goal is to improve the ratio over time.
4. Time from Publication to Discovery and Indexation
Track how long new pages take to be discovered and indexed.
For example:
Before optimisation:
Average discovery time: 5 days
After optimisation:
Average discovery time: 24 hours
This can be one of the clearest indicators that your technical improvements are helping search engines find important content faster.
You can monitor individual pages through Google Search Console’s URL Inspection tool.
For large sites, record the publication date and first indexation date in a spreadsheet or analytics system.
5. Crawled but Not Indexed URLs
Monitor the number of URLs appearing as:
Crawled – currently not indexed
This number will rarely be zero.
But it should not grow continuously without explanation.
If it rises rapidly, Googlebot may be spending resources on pages that Google ultimately does not consider valuable enough to index.
Investigate recurring URL patterns rather than reviewing every page individually.
A Monthly Crawl-Budget Maintenance Routine
Crawl-budget optimisation is not a one-time technical project.
Large sites constantly create new URLs.
Plugins generate parameters. Developers change routes. Products expire. Filters expand. Redirect chains accumulate.
A monthly routine prevents crawl waste from returning.
Week 1: Review Search Console Crawl Stats
Check:
- URLs crawled per day
- Average response time
- Crawl requests by response code
- Crawl requests by file type
- Crawl requests by Googlebot type
Look for sudden changes.
A sharp increase in 404 responses may indicate broken internal links or a migration problem.
A sharp increase in crawl response time can suggest a server or application issue.
Week 2: Audit Index Coverage
Review issues such as:
- Crawled – currently not indexed
- Discovered – currently not indexed
- Duplicate without user-selected canonical
- Soft 404
- Not found (404)
Export problem URLs and group them by pattern.
Do not fix URLs individually if thousands share the same cause.
Fix the template, routing rule, plugin, or CMS behaviour creating them.
Week 3: Review Sitemaps
Check that sitemap URLs:
- Return a
200response - Are canonical
- Are indexable
- Do not redirect unnecessarily
- Are still commercially or editorially relevant
Remove URLs that no longer belong in the sitemap.
Week 4: Crawl Your Own Site
Use Screaming Frog or another crawler.
Check:
- Redirect chains
- Broken internal links
- Orphan pages
- Parameter URLs
- Duplicate pages
- Click depth
- Canonical errors
Compare results month to month.
A healthy site should become cleaner and easier to crawl over time.
Common Crawl-Budget Optimisation Mistakes
Crawl-budget optimisation can backfire when implemented too aggressively.
The goal is not to block Googlebot from your site.
The goal is to help Googlebot spend more time on valuable URLs.
Mistake 1: Blocking URLs in Robots.txt That Need to Be Deindexed
Blocking crawling does not automatically remove a URL from Google’s index.
If a URL is already indexed and you block it in robots.txt, Googlebot may be unable to crawl the page and see a noindex directive.
If you want a page removed from the index, use the appropriate removal and indexing controls rather than assuming robots.txt alone will deindex it.
Mistake 2: Removing Useful Pagination
Pagination can still be necessary for discovery.
If you completely remove page 2, page 3, and page 4 links, Googlebot may lose access to older content.
Instead, control whether those pages need to be indexed while preserving useful crawl paths where necessary.
Mistake 3: Canonicalising Everything to the Homepage
Some site owners attempt to solve duplication by adding homepage canonicals to every low-value URL.
This is incorrect.
Canonical tags should point to the closest equivalent page.
A filtered shoe page should usually canonicalise to the relevant shoe category or product page, not the homepage.
Incorrect canonicals create confusing signals and may simply be ignored.
Mistake 4: Removing URLs That Have Backlinks
Before deleting or permanently removing any page, check whether it has inbound links.
A seemingly useless old article may still possess valuable authority.
If it has meaningful backlinks, consider redirecting it to the most relevant replacement rather than removing it without preserving that value.
Mistake 5: Obsessing Over Crawl Budget on a Small Website
Most small sites do not have meaningful crawl-budget problems.
If your site contains only a few hundred pages and Google discovers and indexes them consistently, focus first on:
- Content quality
- Search intent
- Internal linking
- Technical SEO
- Backlinks
- Conversion performance
Crawl-budget optimisation becomes more important when:
- Your site contains tens or hundreds of thousands of URLs
- New content takes a long time to be discovered
- Googlebot spends significant activity on parameters or duplicates
- Your server is slow
- Index coverage shows substantial crawl waste
Do not introduce unnecessary technical complexity where no real crawl problem exists.
Frequently Asked Questions About Crawl Budget
What Is Crawl Budget?
Crawl budget describes the amount of crawling activity Googlebot allocates to your website within a given period.
It influences how many URLs Google is willing and able to request from your site.
Large sites, slow servers, and duplicate URL structures are more likely to experience crawl-efficiency problems than small, well-structured websites.
Does Crawl Budget Affect Rankings?
Crawl budget does not directly determine where a page ranks.
However, a page cannot rank if Google has not discovered, crawled, and indexed it.
Poor crawl efficiency can therefore delay the discovery and indexation of important pages, particularly on very large websites.
How Do I Know If I Have a Crawl-Budget Problem?
Common warning signs include:
- New pages take several days or weeks to be discovered
- Large numbers of URLs appear as crawled but not indexed
- Googlebot spends significant activity on filters and parameters
- Crawl response time is high
- Important sections are crawled infrequently
- Log files show repeated crawling of low-value URLs
If your site has only a few hundred pages and Google crawls them regularly, crawl budget is unlikely to be your main SEO problem.
Can I Increase My Crawl Budget?
You generally cannot simply request a larger crawl budget.
The practical approach is to improve efficiency.
You can help Googlebot spend more of its crawling activity on useful pages by:
- Improving server response speed
- Removing low-value URLs from sitemaps
- Reducing duplicate URLs
- Fixing redirect chains
- Improving internal linking
- Controlling unnecessary crawl paths
- Keeping important content current and accessible
A faster, cleaner, and more authoritative website is easier for search engines to crawl efficiently.
Does Robots.txt Save Crawl Budget?
It can, when used correctly.
robots.txt can prevent Googlebot from crawling low-value areas such as internal search pages, staging environments, or administrative sections.
However, robots.txt should not be treated as a substitute for noindex.
Blocking crawling and controlling indexation are separate functions.
Should Pagination Pages Be Indexed?
It depends on their value.
Pagination pages that exist only to help users browse deeper archives often do not need to rank independently.
However, pagination can still provide important discovery paths to older content.
Do not block pagination so aggressively that search engines can no longer discover valuable pages.
How Often Should I Audit Crawl Budget?
For large e-commerce, marketplace, publishing, and SaaS sites, review crawl statistics monthly.
Run deeper technical audits quarterly or after major website changes.
Small websites can usually review crawl efficiency every three to six months unless they experience discovery or indexation problems.
Does Page Speed Affect Crawl Efficiency?
Server performance can affect how efficiently Googlebot accesses your website.
If your server responds slowly or regularly times out, search engines may crawl fewer pages successfully.
Improving server response time, caching, and CDN performance can therefore improve overall crawl efficiency.
What Is the Difference Between Crawling and Indexing?
Crawling means Googlebot fetched the page.
Indexing means Google decided to store the page and potentially make it eligible to appear in search results.
A page can be crawled without being indexed.
That is why crawl-budget optimisation must be paired with strong indexation signals, canonicalisation, useful content, and sound technical SEO.
Conclusion: Make Every Googlebot Visit Count
Crawl-budget optimisation is ultimately an efficiency problem.
Google has finite crawling resources, and large websites need to ensure crawling activity is directed toward pages that can generate search visibility, traffic, and revenue.
Start by identifying waste.
Check Google Search Console. Review pages crawled but not indexed. Analyse parameter URLs, pagination, redirects, server speed, internal links, and sitemap quality.
Then fix the largest sources of waste first.
For most large websites, the biggest gains come from:
- Removing low-value URLs from XML sitemaps.
- Improving server response time.
- Controlling parameter and filter URLs.
- Consolidating duplicate content.
- Strengthening internal links to priority pages.
Do not optimise crawl budget simply to achieve a higher crawl count.
The objective is not to make Googlebot crawl more.
The objective is to make Googlebot crawl better.
When the right pages are discovered quickly, indexed consistently, and revisited at the appropriate frequency, crawl budget stops being a hidden technical constraint and becomes part of a more efficient SEO system.